はじめに|企画は私、プロンプトはChatGPT
『昭和世代のかくし芸』は、55〜70歳の男性5人が、旅館の宴会場で、かくし芸のダンスを披露する15秒のAI動画です。最後に、左端の人がかつらを外します。生成は2回、制作にかかった時間は30分でした。
脚本は先に私が作っていたので、制作時間は短くて済みました。この動画は、ChatGPTとの共同制作です。企画と脚本は私で、企画どおりの動画を作るための指示文(プロンプト)を、ChatGPTに作ってもらいました。
動画の生成は、動画も作れるAIのGrokです。映像は編集しておらず、音声もGrokが生成したままです。動画編集アプリのCapCutで、字幕を付けただけです。
この記事では、1回目と2回目のプロンプトの全文と、直した点、公開後の数字をお伝えします。
1回目のプロンプト
1回目のプロンプトは、次のとおりです(ChatGPTが作成)。英語のまま載せていますが、そのままGrokに貼って使えます。台詞だけは、日本語で入れています。
構成は、おおまかに「設定→登場人物→秒数ごとの動き→禁止事項」の順です。5人の位置と顔を固定して、左端の人だけが白いかつらをかぶるように指示しています。
Create a single continuous 15-second photorealistic Japanese comedy short film, vertical 9:16. Exactly FIVE Japanese men aged 55–70 in traditional yukata robes, standing in ONE fixed horizontal row in a nostalgic Japanese ryokan banquet room with tatami flooring and warm lighting. All five are cheerful, lovable, ordinary middle-aged-to-elderly men, not professional dancers.

CRITICAL CHARACTER CONTINUITY:
Exactly five men from beginning to end. Their positions never change. No additional people, no duplicates, no morphing, no swapping faces or bodies. Camera stays in a stable frontal wide shot showing all five men, including their heads and feet.

The man at the FAR LEFT of the SCREEN (viewer's left) is the ONLY person wearing a removable, slightly old-fashioned WHITE WIG. Beneath his wig he has a clearly bald scalp. The other FOUR men have their own natural, visibly different hairstyles: short black hair, salt-and-pepper hair, short gray hair, and neatly combed dark hair. They NEVER wear wigs. Their hairstyles and hair colors remain exactly the same throughout the entire video. Only ONE wig exists in the entire scene.

TIMELINE:
0–3 seconds: Five men stand proudly in a row, grinning confidently. The man in the center enthusiastically shouts in natural Japanese: "見せてやる!昭和の本気!" They strike exaggerated, slightly ridiculous dance poses.

3–10 seconds: Upbeat, playful retro Japanese disco-inspired instrumental music begins. All five perform the SAME deliberately simple, awkward, old-fashioned dance: two small side steps, arms swinging left and right, synchronized knee bends, then both hands raised overhead while swaying. The choreography looks more like a charming amateur school performance than a polished disco routine. Their timing is slightly imperfect but they are genuinely delighted, laughing and dancing with total confidence. The humor comes from the contrast between their serious enthusiasm and their hilariously uncool choreography. They stay in their original positions. NO spinning, crossing, jumping, costume changes, or complex movements.

10–13 seconds: The music stops sharply. All five freeze in a triumphant final pose. ONLY the man at the far left gently removes his SINGLE WHITE WIG with his own hand, revealing his bald head. He smiles proudly and holds the wig in one hand. The other four men remain fully haired, surprised and amused. No other wig appears.

13–15 seconds: One of the FOUR men with natural hair points at his own hair and delivers the punchline in Japanese, with playful comic timing: "全員ハゲじゃないからな!" The five men burst into friendly laughter. End on a clear wide shot with all five men visible.

VISUAL STYLE:
Warm, realistic Japanese ryokan atmosphere, natural facial expressions, authentic human anatomy, believable fabric motion, charming Showa-era nostalgia, lighthearted family-friendly comedy. Clear, readable gestures and precise comic timing. Natural camera exposure, cinematic realism, no cartoon aesthetics.

ABSOLUTE RESTRICTIONS:
Exactly five men. Exactly one white wig, worn only by the far-left man until the final reveal. The far-right man must NEVER wear or acquire a white wig. No other man becomes bald. No changing hairstyles or hair colors. No sudden costume changes. No extra hands, extra limbs, duplicated heads, floating hairpieces, or objects appearing from nowhere. No scene cuts, no camera angle changes, no zooms, no subtitles, no captions, no text overlays, no logos, no watermarks. Keep the entire scene continuous and visually coherent for the full 15 seconds.
1回目の動画は、公開していません。問題点は、3つでした。左端の人のかつらが白髪になっていたこと、5人の顔が似ていたこと、そして、5人が一定の場所から動かず、動きが少なかったことです。ほかは、2回目と大きくは変えていません。
2回目のプロンプトで直したこと
私が改善してほしい点をChatGPTに伝えて、ChatGPTが2回目のプロンプトに修正してくれました。変えた点は、次のとおりです。
| 項目 | 1回目 | 2回目 |
|---|---|---|
| かつら | 白(左端の人だけ) | 黒(左端の人だけ) |
| 5人の書き方 | 髪型だけ書く | 顔・体型・髪を、1人ずつ書き分ける |
| 動き | 位置を固定 | 踊りながら前に出てきて、最後はアップになる |
| 台詞 | 冒頭の台詞のほか、最後にChatGPTが足した台詞がある(私の指定ではありません) | 冒頭の1行だけ |
| 結び | 台詞のあとに笑う | 全員の笑いで終わる |
動きが少ないので、5人が前に出てくる指示を足しました。縦型の画面で、スマホで自然に撮ったような映像に見えるよう、工夫もしています。
2回目のプロンプトは、次のとおりです。文末の「\」は、貼り付け時の改行記号です。そのまま貼っても、消しても、かまいません。
Create a photorealistic 15-second Japanese comedy video, vertical 9:16, in ONE continuous shot.

SETTING:\
A nostalgic Japanese ryokan banquet room with tatami flooring and warm lighting. Exactly FIVE Japanese men aged 55–70 wear different yukata robes. They are cheerful old friends enjoying themselves.

CHARACTERS (screen left to right):

1. Far left: Chubby, round face, thick eyebrows, short natural-looking BLACK HAIR. His black hair is actually a removable wig hiding a bald scalp.
2. Tall, slim man with a narrow face and natural salt-and-pepper hair.
3. Stocky man with a square face, small eyes and short gray hair.
4. Medium-build man with glasses, an oval face and neatly combed dark hair.
5. Lean older man with deep wrinkles, prominent nose and short silver-gray hair.

All five must have clearly DIFFERENT faces, physiques and hairstyles. Never change their identities or positions.

0–2 SECONDS:\
The five men face the camera confidently. The center man enthusiastically shouts in Japanese:\
「見せてやる!昭和の本気!」\
They immediately begin dancing.

2–11 SECONDS:\
Playful, upbeat retro Japanese dance music starts.

All five perform a hilariously awkward, old-fashioned amateur dance. They swing their arms, bend their knees, sway side to side and raise both hands. Their movements resemble a school performance rather than professional dancing.

They believe they look incredibly cool and enjoy every second, smiling and laughing.

IMPORTANT: While dancing, all five gradually WALK FORWARD TOWARD THE CAMERA with three small synchronized steps. Their bodies become noticeably larger in the frame. Keep all five visible and maintain their original left-to-right order.

Their dancing is energetic but simple. Slightly imperfect synchronization makes it naturally funny.

11–13 SECONDS:\
The music stops. All five strike a proud final pose.

ONLY the FAR-LEFT man playfully removes his natural-looking BLACK WIG with one hand, revealing his bald head. He holds the single wig visibly in his hand.

The other four men retain their natural hair and react with surprise and amusement.

13–15 SECONDS:\
All five burst into warm, spontaneous laughter. The bald man laughs happily with his friends. One claps, another bends forward laughing. End with all five sharing a joyful moment.

STYLE:\
Authentic Japanese faces, natural skin texture, distinct personalities, realistic movement, nostalgic Showa atmosphere, warm cinematic lighting. Funny, affectionate and family-friendly.

STRICT RULES:\
Exactly five men throughout. Exactly ONE BLACK WIG, worn ONLY by the far-left man until the final reveal. No white wigs. No other wigs or bald men. No changing faces, hairstyles, clothing or positions. No extra people or duplicated body parts. No scene cuts. No subtitles, captions, text or watermarks. No dialogue after the opening line. All five must gradually move toward the camera while dancing. Finish with joyful group laughter.
公開後の数字
YouTubeは、公開から約31時間たった時点で、視聴回数が1,289回でした(2026年10月26日の夜、YouTubeのアナリティクス)。動画は15秒ですが、YouTubeの表示は16秒です。平均視聴時間は24秒で、動画の長さより長くなっています。視聴者の年齢は、45歳以上が合わせて約6割でした(年齢は、アカウントの申告などに基づく数字です)。
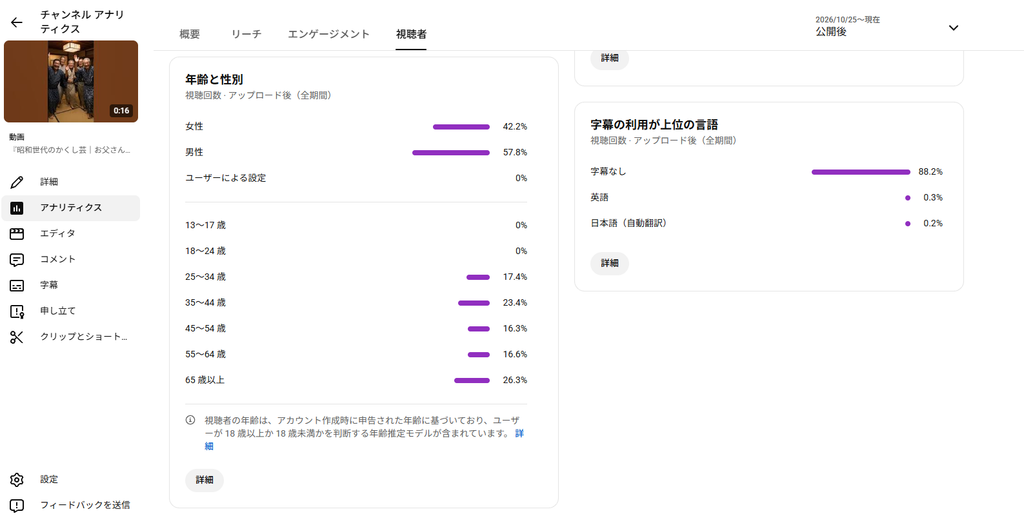
YouTube Studio:視聴者の年齢と性別(公開後の全期間)
TikTokは、投稿から約2日たった時点で、動画視聴数が223回でした。平均視聴時間は8.25秒で、最後まで見た人(フル視聴)は21.7%です。
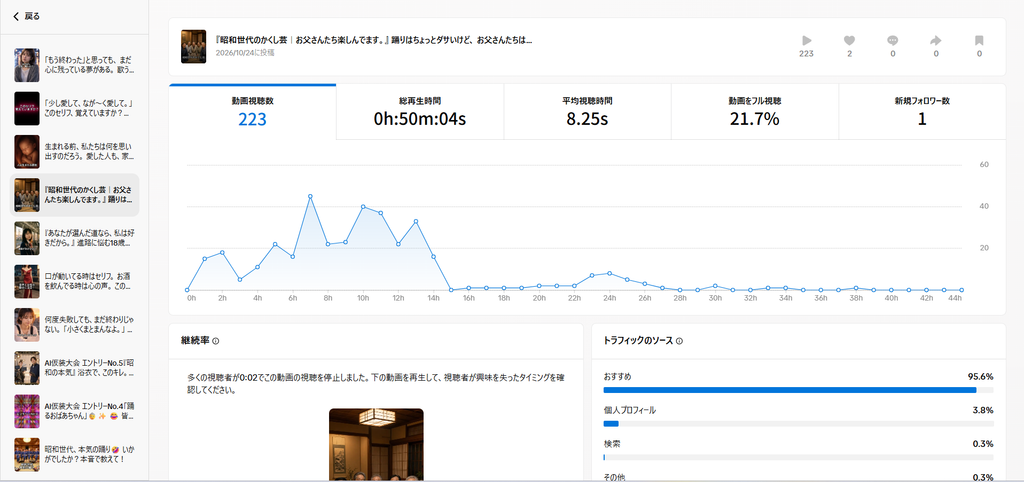
TikTok Studio:『昭和世代のかくし芸』の視聴データ
YouTubeの方が、年齢や、どこまで見られたかの割合(維持率)など、詳しい数字を見ることができました。2つは、投稿してからの時間が違うので、数字は並べて比べていません。
まとめ|問題点を言葉にして、次の指示文に入れる
1回目で出た問題は、「かつらが白い」「顔が似ている」「動きが少ない」の3つでした。それを2回目のプロンプトに1つずつ反映して、30分、2回の生成で完成しました。
違う顔を出したいときは、1人ずつ書き分ける。動きを出したいときは、動きの方向と歩数を書く。この2つが、今回の直し方でした。何を直したいかを決めるのは私で、それを指示文にするのがChatGPTです。
まずは1回生成して、問題点を言葉にして、次のプロンプトに書き足してみてください。前の記事に、プロンプトを1本で完成させる考え方を書きました。
AI動画は、1本のプロンプトで作るか、パーツを編集するか。脚本を決めてから選んでいます
作品は、YouTubeとTikTokで公開しています。
コメント